Data Engineer Resume Example: Pipelines, Reliability and Measured Results
by Larbi SahliLast Updated
Describe data pipelines, modeling, cloud work and reliability accurately. Includes a fictional resume, measurement examples and guidance for junior and senior roles.
Users have landed jobs at
- 1Password
- OpenAI
- Notion
- justworks
On this page
A data engineer resume is easier to assess when it follows the data: the source, ingestion method, transformation, destination and downstream use. Then explain what you built or operated, how you checked correctness, and what evidence supports any performance claim.
A list of tools cannot show the difference between a personal pipeline and a production platform. This guide demonstrates that distinction with a fictional resume, role-specific bullet examples and ways to report volume, freshness, reliability and cost without inventing numbers.
A Clear Structure for a Data Engineer Resume
Put relevant work where a reader can find it, but do not build the resume around a supposed universal seven-second screen. A clear summary, grouped skills and specific experience or project entries provide a practical structure. Adapt their order to your strongest evidence and the vacancy.
- Header: current contact information and relevant, authorized public project links; avoid unnecessary personal details.
- Summary: relevant pipeline work, core skills and accurate scope. A quantified result is optional.
- Skills: group languages, data modeling, storage, orchestration and operational tools you actually used.
- Experience: keep roles and dates clear; use bullets that distinguish what you built, tested or operated.
- Projects: include relevant personal, academic or volunteer work with accurate labels and test conditions.
- Education and training: state exact completed qualifications and credential status; put relevant requirements where they are easy to find.
Use enough space to explain relevant work without repeating the same pipeline duties. There is no fixed five-year cutoff for a second page. The page-length guide explains the tradeoff between detail and readability.
Use recognizable section headings and inspect reading order after export. Columns, text boxes and graphics can complicate some parsers, but no layout guarantees success or failure in every system. A skill name and a concrete example communicate more than an unexplained dot rating. Follow the application’s file requirements and check extracted fields if a preview is offered.
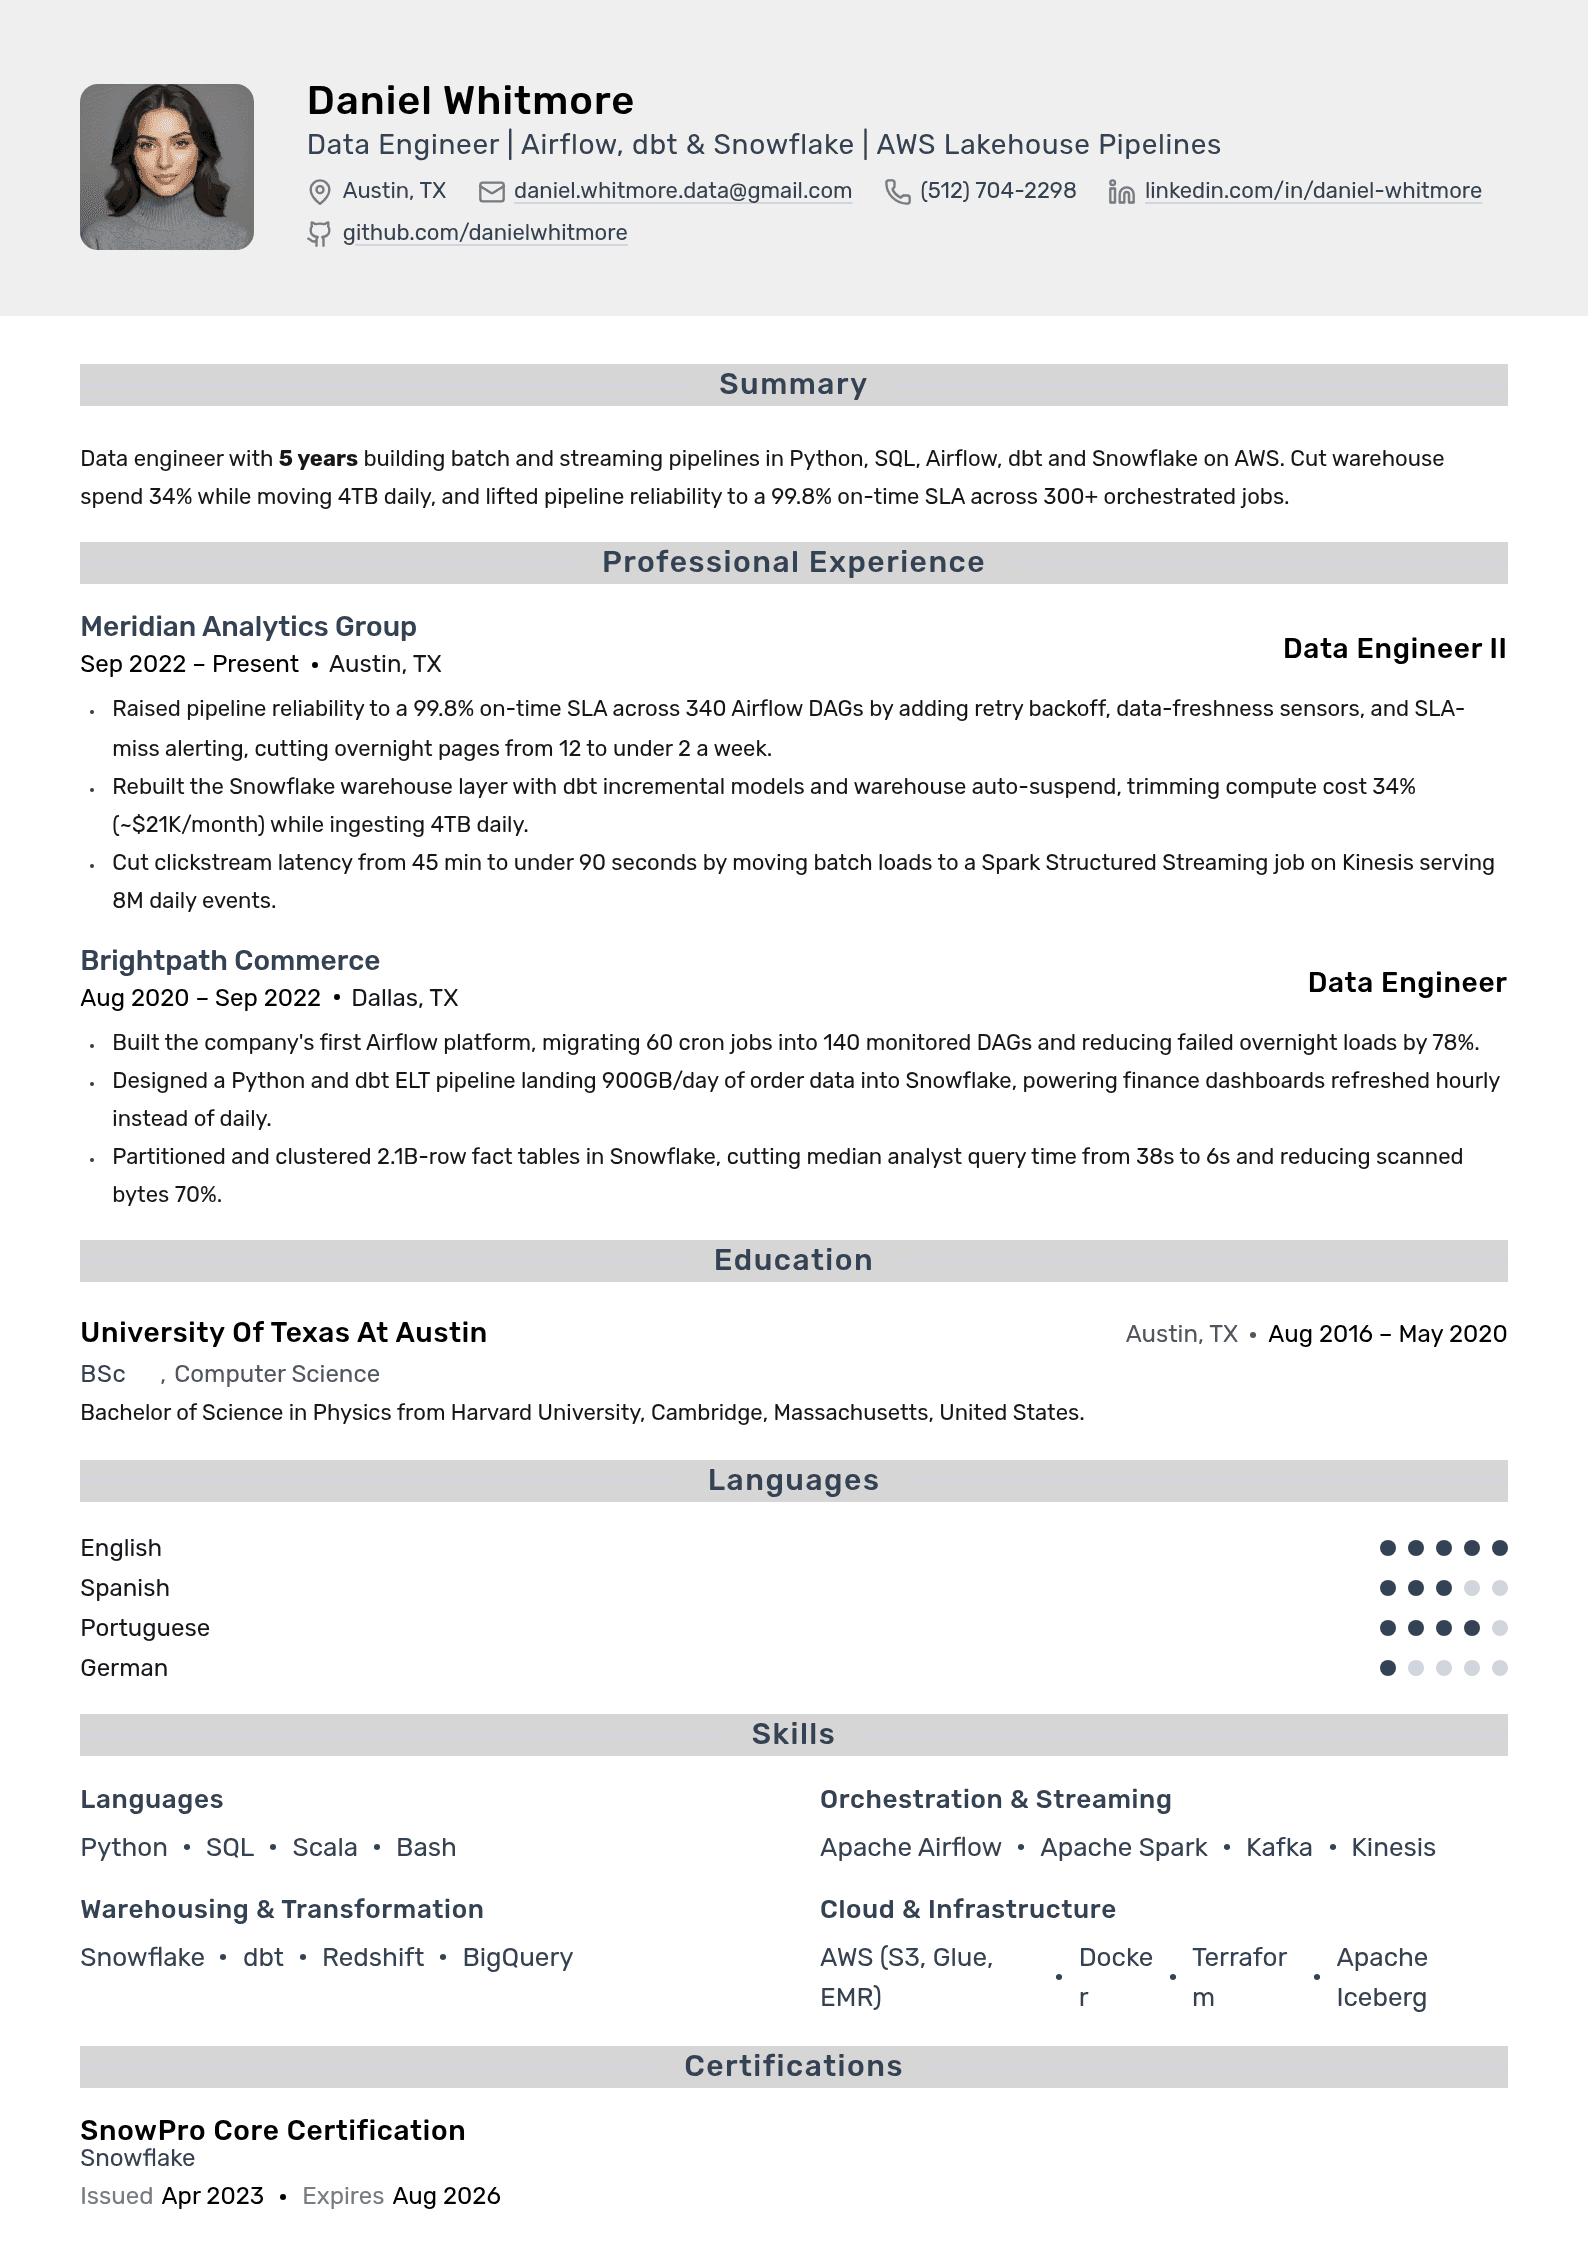
Data engineer resume example (mid-level)
Fictional example: Daniel Whitmore and the employers, education, project, training and recognition below are invented for illustration. The resume is not a real applicant record, measured case study or hiring result. Contact links are placeholders; replace all details and ratings with your own evidence.
The sample connects batch orchestration, transformations and monitoring to distinct tasks. It avoids presenting invented terabytes, savings or reliability percentages as verified achievements.
Data Engineer resume keywords
Compare these possible terms with the actual vacancy. This is an editorial checklist, not measured frequency data or an ATS formula. Include only work you can describe accurately.
| Keyword | Type | Where to put it |
|---|---|---|
| SQL | Language | Describe modeling or query work |
| Python | Language | Connect it to ingestion, transformation or automation |
| Apache Airflow | Workflow tool | Describe tasks, dependencies and operational checks |
| Apache Spark | Processing framework | Name the workload and execution context |
| Snowflake | Data platform | Describe actual models, queries or operation work |
| dbt | Transformation tooling | Explain models, tests or documentation authored |
| Cloud platform | Platform | Name relevant services and your responsibilities |
| Apache Kafka | Event platform | Describe producer, consumer or operational work |
| BigQuery | Data platform | Identify production or project context accurately |
| Terraform | Infrastructure tooling | Explain resources or configuration maintained |
| Dimensional modeling | Practice | Describe facts, dimensions and use cases |
| CI/CD | Practice | Explain test and deployment steps |
| Relevant certification | Credential | State exact issuer name, earned date and status |
| Relevant training | Training | Distinguish a course from certification |
| On-time completion | Measurement | Define the deadline, run population and period |
| Data volume | Measurement | State units, period and what was counted |
A tool can appear in skills and in the relevant project or job, but repeating it does not establish proficiency. Use the resume keyword scanner to compare wording, then decide whether a suggested term describes experience you actually have.
What the Example Demonstrates
The summary defines the work. It names pipelines, transformations and operation tasks rather than claiming expertise from a product list. Use dates or an accurate experience total, and add a result only when you have evidence. See the summary guide for drafting patterns.
Skills have context. Grouping languages, warehouse tools and workflow systems helps the reader locate relevant experience. You can include a tool learned in a project if the project context and depth are clear; do not imply production ownership from a tutorial.
Bullets distinguish responsibilities. Writing a transformation, designing a data model, operating a schedule and responding to an incident are different contributions. State which you performed and how the work was checked.
Technical terms stay precise. Apache Airflow describes workflows through tasks, dependencies and schedules. Name the job it orchestrated rather than implying the orchestrator itself did every transformation or processed a continuous event stream.
Data engineer resume example (senior and lead)
For a senior or lead role, explain the decisions and responsibilities that were yours. Implementation remains valuable; a job title alone does not prove architecture authority, people management or budget ownership.
- Decision scope: explain the options you evaluated, the tradeoff and who approved the choice. Do not claim architecture ownership when you implemented part of a design.
- Cost work: distinguish query optimization, capacity changes and negotiated pricing. Compare like-for-like workloads before claiming savings.
- Operational responsibility: identify systems or teams supported, incident response duties and any mentoring; distinguish these from direct people management.
- Migration work: state your part in mapping, testing, backfill, cutover or rollback planning, plus the validation that established readiness.
Select the balance of technical and leadership evidence required by the role. A platform lead might explain design reviews and operational responsibility, while a hands-on specialist might emphasize modeling or query work. There is no universal rule that one third of the bullets must be technical or that cost savings must lead every senior resume.
Pipeline and Data Platform Terms to Consider
Different vacancies emphasize different data systems. The table below groups possible terms by their function; it does not rank market demand or claim that any product appears in nearly every posting. Read the actual responsibilities before choosing which skills to foreground.
| Area | Possible terms | Evidence to explain |
|---|---|---|
| Languages and models | SQL, Python, ETL, ELT, dimensional modeling | Transformations, model decisions and validation |
| Storage and warehousing | Snowflake, BigQuery, Redshift, Databricks | Actual storage, query or warehouse responsibilities |
| Workflow and transformation | Airflow, Dagster, Prefect, dbt | Distinguish orchestration from the transformation work |
| Distributed processing | Spark, PySpark | Workload, execution environment and tuning method |
| Streaming | Kafka, Kinesis, Flink, Spark Structured Streaming | Event flow, recovery, state or timing behavior |
| Engineering practices | CI/CD, data quality, access controls, Terraform | Changes implemented, tests, review and operational ownership |
Use the vacancy’s recognizable terminology when it accurately fits your work. ETL and ELT describe different ordering of transformation and loading; name the process you used instead of adding both solely for a match. Explain where transformation occurred and which system performed it.
There is no universal optimal skill count or exact-string ATS rule. Remove unsupported tools and describe relevant ones in context. The resume keyword guide gives a practical comparison method.
How to list cloud platforms (AWS, GCP, Azure) effectively
Name the cloud services you used and what you did with them. “Loaded approved source files into object storage and transformed them for warehouse reporting” is more informative than “cloud expert”; add actual service names where relevant. Distinguish configuring infrastructure from consuming a managed service.
You may list more than one cloud when your evidence supports it. Label lab or coursework exposure as such, and do not imply that knowledge of one product means production experience with another. Transferable concepts are useful, but employers decide whether they meet the role’s requirements.
Check credential titles and status with the issuer. For example, Microsoft’s Azure Data Engineer Associate credential page records retirement on March 31, 2025; it should not be recommended as a currently available exam. If listing a historical credential, state its earned date and status accurately. Credential placement depends on relevance, and a certificate does not establish production experience.
Quantifying data volume and processing speed in your bullets
Measurements can clarify scale and results if their definitions are consistent. Before adding a number, record its source, period, denominator or unit, and whether sharing it is permitted. These categories answer different questions:
- Volume: rows, events or bytes over a stated period; specify whether the figure refers to source, stored or processed data.
- Time: distinguish job runtime, event-to-availability latency and age of the latest usable data.
- Cost: identify the service, billing period and workload basis; separate compute from storage and contractual discounts.
- Reliability and quality: define eligible runs, deadlines, failures and quality checks instead of calling every percentage an SLA.
- Scope: explain pipelines, models or downstream consumers without counting the same work multiple ways.
Hypothetical calculation: a comparable batch falls from 60 minutes to 45 minutes. That is a 15-minute reduction, or 25% of the original runtime. It does not prove a 25% reduction in cost or end-to-end data freshness; those require separate measurements.
Without a result measurement: “Added schema and freshness checks to an order pipeline and documented recovery steps for failed loads.” This is useful evidence without inventing a success-rate improvement.
Success rate, on-time completion and data correctness are different measures. Define eligible runs and late or failed runs, and distinguish an observed rate from a contractual SLA or an internal target. Estimates need a documented basis and an estimate label; adding “roughly” does not make an unsupported number acceptable.
Use platform-specific language. Snowflake documents automatic micro-partitioning, so describe the query, clustering or loading work you actually did rather than implying manual creation of static partitions. Report measured query or cost changes with a comparable workload and explain other changes that affected the comparison.
Review Your Existing Resume Against the Role
Use your existing resume as a starting point, then check whether each bullet names the pipeline stage, contribution and evidence. In Roleframe, organize the relevant experience and review any suggested wording before using it.
For a particular vacancy, compare requirements with your factual record. A missing term may be a wording issue or a skill gap; a tool’s score is not the employer’s ATS score or a hiring prediction. Verify all technical claims, dates and results after AI-assisted editing.
Submit an accepted file format, check text selection and reading order, and inspect the application’s extracted fields where available. A text-based PDF can preserve layout, but parsing depends on the file and system.
Tailoring your resume for specific data engineering roles
Use the vacancy’s responsibilities to choose evidence. A transformation-focused role may value model design and testing; a platform role may emphasize infrastructure and operation; a streaming role may ask for event-time handling or recovery; a distributed-processing role may need tuning and workload analysis. These areas overlap, and no fixed tool list defines every job in a category.
Keep a factual base resume and tailor copies by reordering skills and selecting the most relevant bullets. Preserve titles, dates and the distinction between professional and project work. See tailoring a resume to a job description for the comparison process.
Frequently asked questions
- What is the seven-second resume rule?
It is a popular shorthand, not a universal hiring standard. Make relevant experience easy to locate, but do not assume a fixed review time or that page-two content is never read.
- Should I mention AI tools on a data engineer resume?
If relevant, describe what you used them for and how you checked the output. Do not claim AI will eliminate or protect a job category, or list an LLM pipeline you did not build. Preserve confidentiality and distinguish generated code from verified production work.
- Is data engineering only ETL?
A role may also include modeling, orchestration, streaming, quality checks or platform operation. Describe the responsibilities you actually performed; you do not need to claim the full range to make a credible resume.
- Which skills should I list?
Choose from the vacancy and your evidence. Identify relevant languages, storage systems, workflow tools and engineering practices, with context for their use. There is no universal stack or minimum number of products for every data engineering role.
- Should the resume be one page or two?
Use the space needed for relevant, distinct evidence and follow application instructions. Remove repetition before reducing readability. Career years alone do not determine the answer.
- How do I apply without paid data engineering experience?
Use clearly labeled personal, academic or volunteer projects. Explain the data source, stages, test conditions and limitations. A reproducible small pipeline can show design and validation without being described as production employment; check current service pricing before choosing hosted tools.
- Should I submit a PDF?
Follow the employer’s accepted formats. If submitting a PDF, check text selection, reading order, page breaks and links. Review any parsed fields in the application. Neither PDF nor another format guarantees successful parsing.
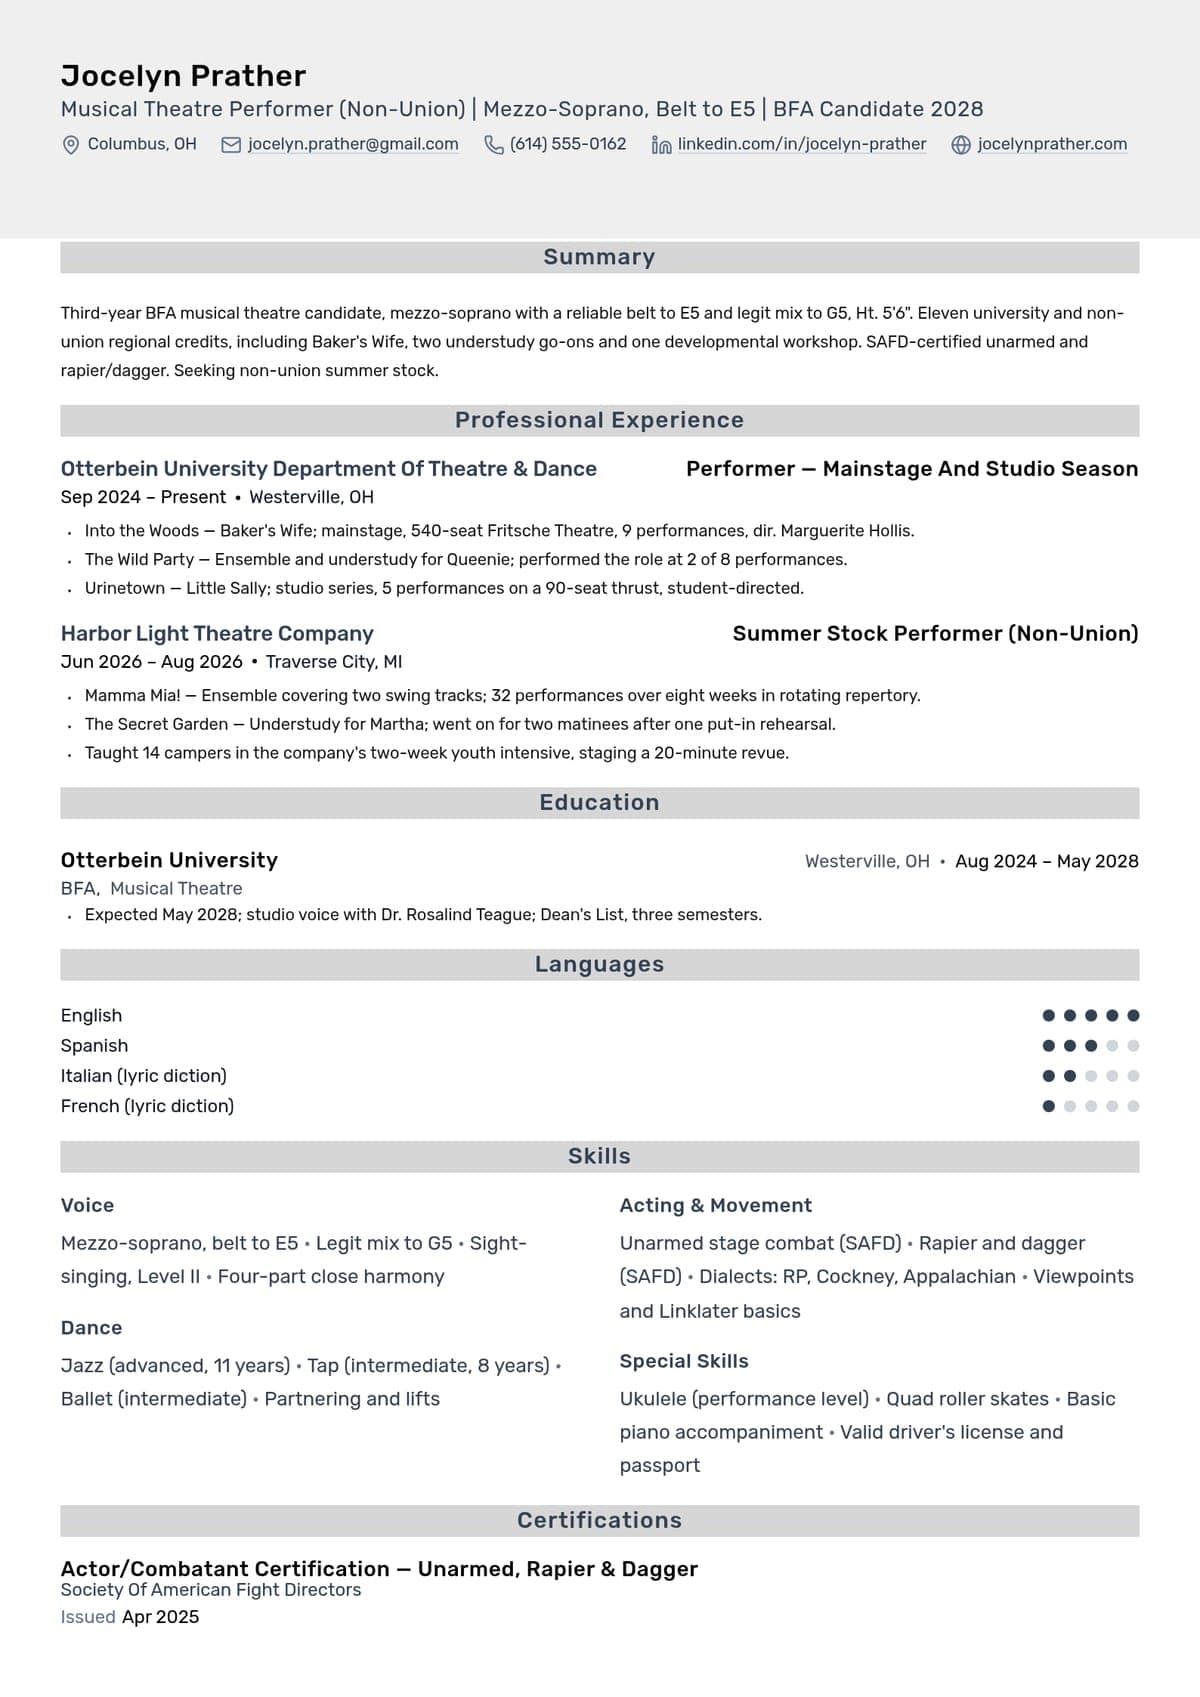

Build yours on the same template.
Every example here is built on a template you can open in the editor. Start from the same layout and write your own experience into it, then download the PDF free, as often as you like.


